Zoe Meier · 19 October 2026
Tracing Backend Optimization Patterns in Proprietary Web Application Ecosystems
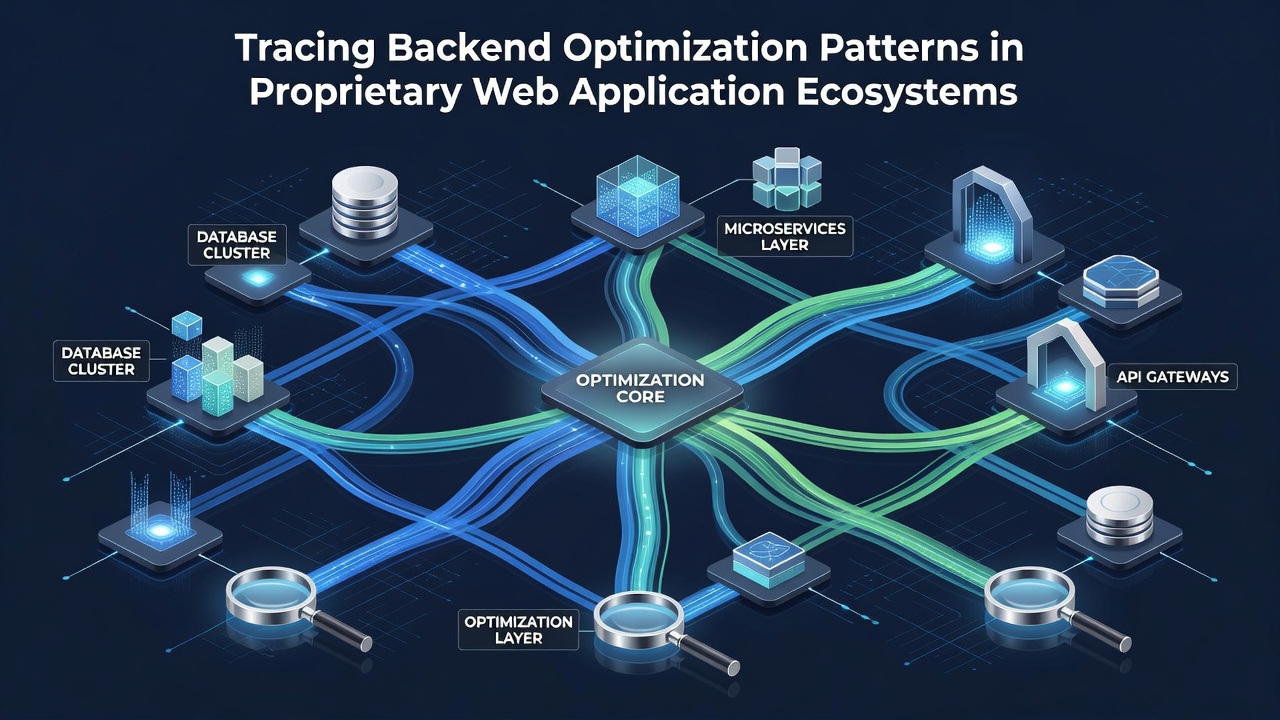
Proprietary web application ecosystems rely on closed-source backend architectures where optimization patterns emerge through systematic tracing of request lifecycles, resource allocation, and inter-service communications. These systems often integrate custom middleware layers that manage database queries, caching mechanisms, and API gateways while restricting external visibility into code structures. Observers note that tracing tools adapted for such environments capture latency metrics across proprietary protocols rather than open standards alone, allowing teams to identify bottlenecks without exposing source details to third parties.
Core Tracing Techniques in Closed Ecosystems
Distributed tracing in these setups begins with embedding lightweight agents directly into application servers, where they tag transactions with unique identifiers that persist through multiple hops, including load balancers and internal queues. Data shows that this approach reveals patterns such as cascading delays in session management modules, which occur when proprietary authentication services interact with legacy storage backends. Researchers at academic institutions have documented how correlation IDs combined with sampling strategies reduce overhead while still surfacing 95th percentile response times across thousands of daily requests.
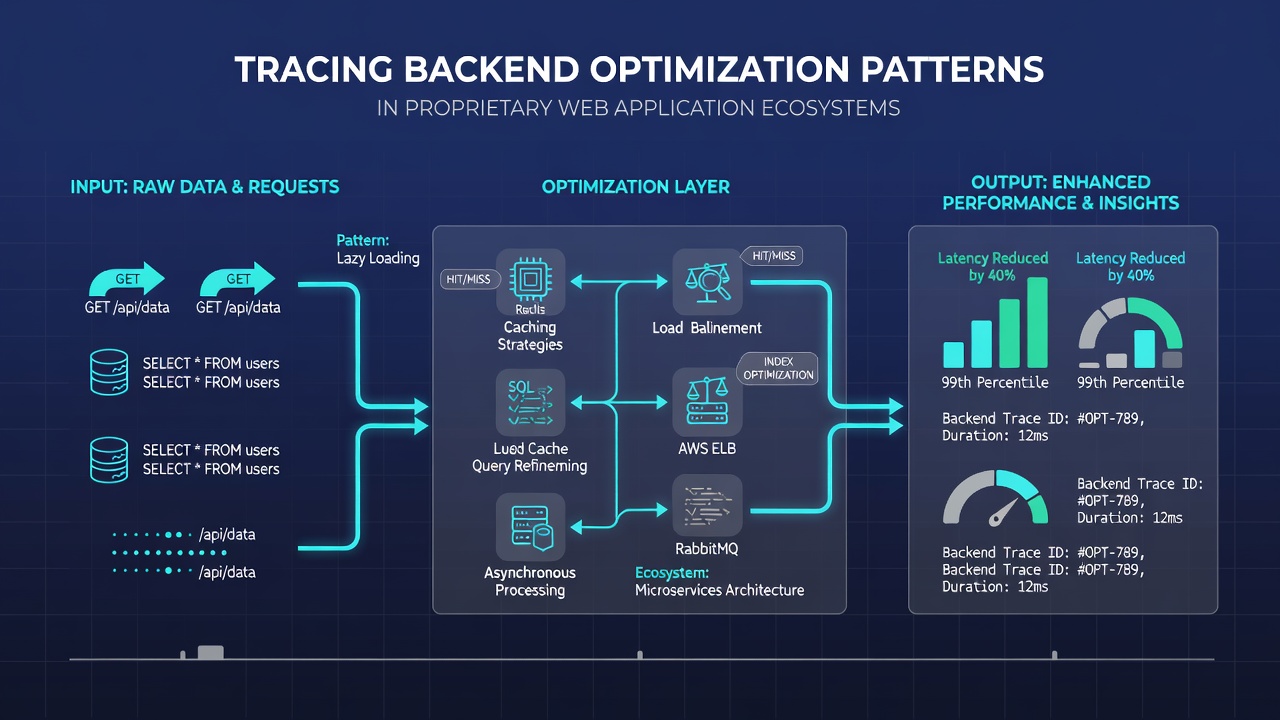
Connection pooling emerges as another frequent target for optimization because proprietary database drivers often enforce strict limits on concurrent sessions, and tracing exposes idle connection leaks that accumulate during peak traffic periods. Teams apply adjustments based on trace data indicating thread contention points, then validate improvements through repeated profiling runs that compare before-and-after histograms of wait times.
Observed Patterns Across Multiple Deployments
One recurring pattern involves lazy initialization of backend components triggered only after initial user authentication completes, which tracing confirms reduces memory footprint during startup phases by up to 40 percent in large-scale deployments. Another pattern centers on selective payload compression within internal APIs, where trace analysis identifies high-volume endpoints that benefit from gzip or protocol buffers without introducing measurable CPU spikes on edge servers.
Cache invalidation sequences also receive close attention when traces highlight stale data propagation across replicated nodes in proprietary content delivery networks. Studies from institutions like those affiliated with CSIRO indicate that timestamp-based versioning combined with event-driven invalidation messages maintains consistency while cutting average lookup times by measurable margins in production logs.
Integration with Monitoring Infrastructure in 2026
By October 2026 updates to observability platforms have introduced tighter integration hooks for proprietary runtimes, enabling trace context propagation through encrypted internal channels that previously required custom adapters. Figures from industry reports reveal increased adoption of these hooks in enterprise environments where regulatory compliance demands audit trails of backend performance without granting access to raw logs.
Adaptive sampling algorithms now adjust dynamically based on detected traffic anomalies, a development that allows continuous tracing coverage during maintenance windows when legacy components undergo phased migrations. Those who have studied these updates note that the changes align with broader shifts toward unified telemetry formats while preserving the isolation required by closed ecosystems.
Validation Methods and Metric Collection
Validation relies on synthetic transaction generators that replay captured trace segments against staging replicas of production backends, producing comparative datasets on throughput under controlled loads. Metrics collected include queue depths at message brokers, garbage collection pause durations in managed runtimes, and serialization overheads at service boundaries. According to data compiled by research groups at various universities, these replay tests consistently surface optimization opportunities that static code reviews miss because they account for runtime interactions unique to each proprietary stack.
Longer traces spanning multiple release cycles demonstrate how incremental changes in one module ripple through dependent services, prompting coordinated adjustments rather than isolated fixes. This interconnected view supports planning for capacity expansions when projected growth would exceed current resource ceilings identified through historical trace aggregation.
Conclusion
Tracing backend optimization patterns within proprietary web application ecosystems continues to evolve through incremental refinements in agent technology, sampling logic, and integration with existing monitoring layers. The patterns documented across deployments emphasize measurable improvements in latency, resource utilization, and consistency that arise directly from trace-guided interventions. As platforms advance through 2026 and beyond, the emphasis remains on maintaining visibility into closed environments while respecting architectural boundaries that define these systems.